What does a correct answer cost?
The cheapest of nine models cost about 35× less per correct answer than Claude Opus 5.5, for 5 points of accuracy. Routing each request to the cheapest model that was good enough cut cost 82.7% for 1.4 points.
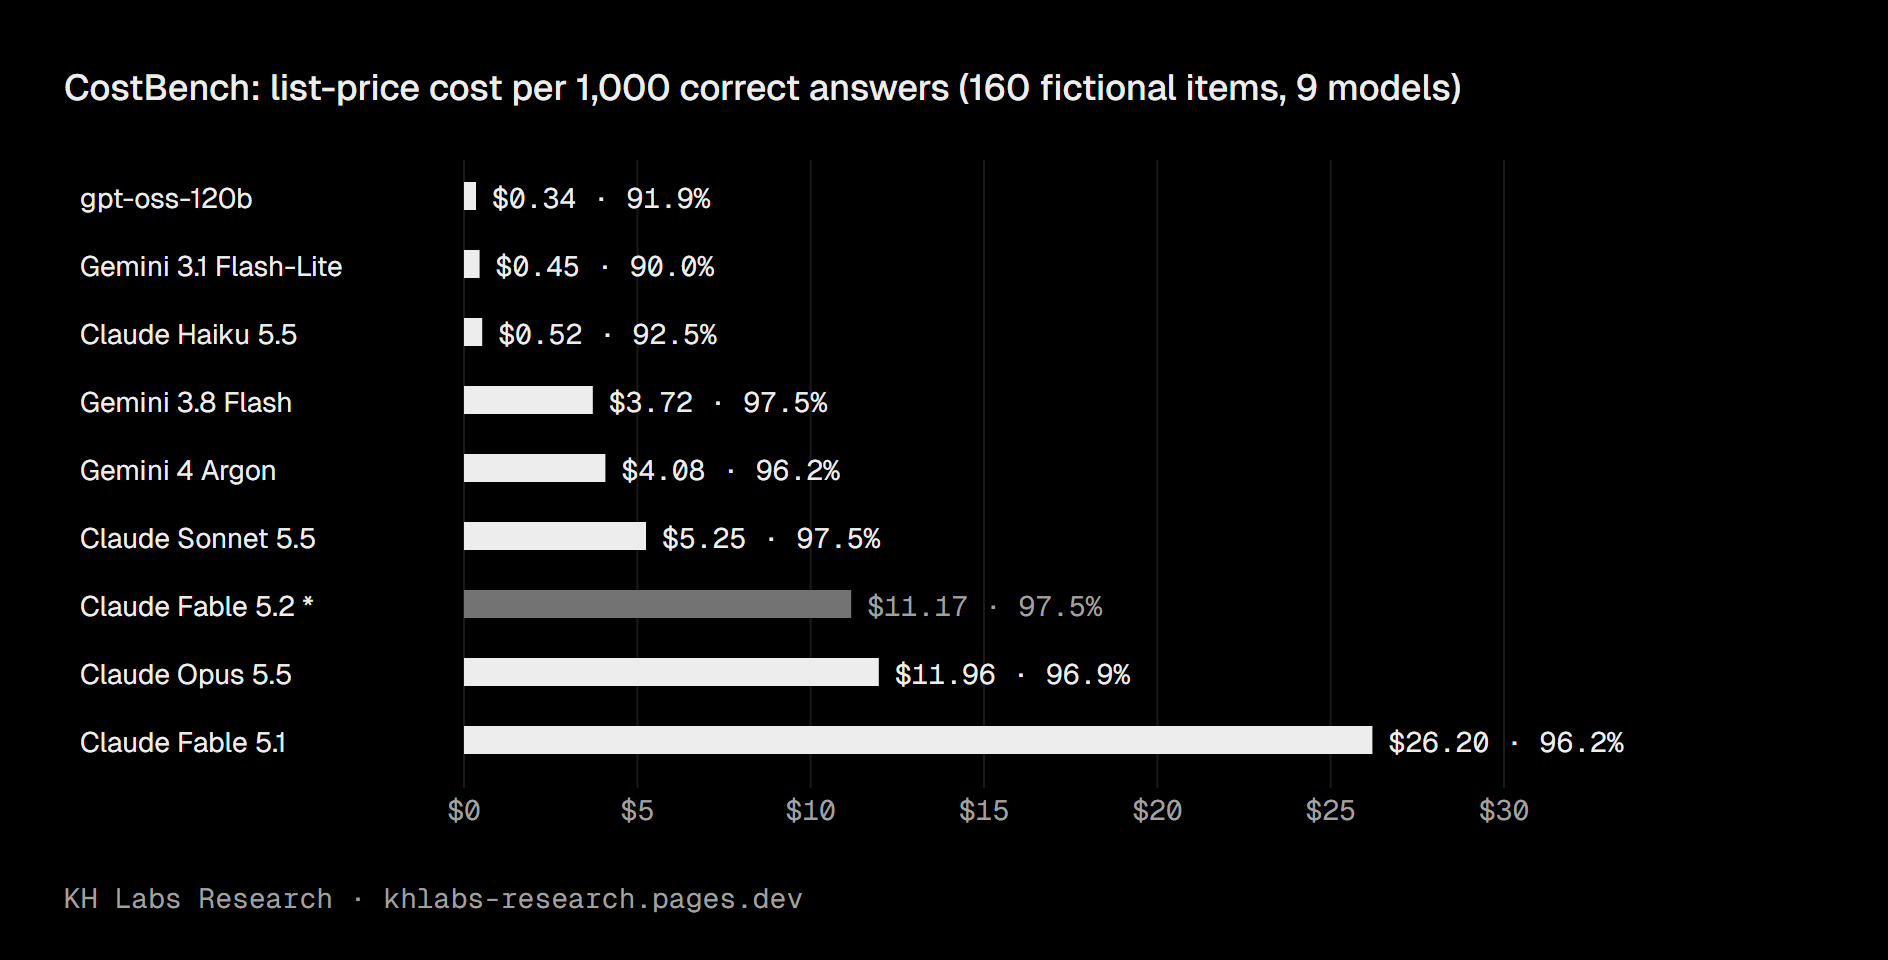
Figure 1. List-price cost of 1,000 correct answers on 160 fictional support and invoice-extraction items per model, with each model’s share of correct answers. * Claude Fable 5.2: estimated tokens (CLI client), so its cost is a lower bound.
Key findings
- About 35× between the cheapest model and Claude Opus 5.5 per correct answer, for 5 points of accuracy. gpt-oss-120b (priced at Groq’s list price): $0.00034 per correct answer at 91.9% correct. Claude Opus 5.5: $0.01196 at 96.9%.
- Among models with measured tokens, Gemini 3.8 Flash is 3.2× cheaper per correct answer than Opus ($0.00372 vs $0.01196) at 97.5% vs 96.9% correct, despite 653 reasoning tokens per answer. Claude Fable 5.1 is the most expensive at $0.02620.
- Routing cut cost by 82.7% for 1.4 points of accuracy. Sending each task segment to the cheapest model that matched the best on a calibration half took the bill from $3.99 to $0.65 per 1,000 answers on held-out items; the accuracy change ranged −4.2 to +0.8 points over 500 random splits.
- Caching: Claude reported 93.1% lower input cost on a repeated prompt prefix; Gemini reported none. Measured from the cached-token counts the API returned, at list prices. gpt-oss-120b: 39%.
- Accuracy is near the ceiling, so price decides. Invoice extraction was 100% for every model; tool calling was 100% for 5 of 8 models that ran it; the spread is in support replies, from 80% (Gemini 3.1 Flash-Lite) to 95%.
Cost against accuracy
Figure 2. Share of correct answers against list-price cost per 1,000 answers (log scale), same 160 items for every model. * Estimated tokens, as in Figure 1.
| Model | Correct | Accuracy | $ / 1k answers | $ / 1k correct | Tokens in / out | Tokens |
|---|---|---|---|---|---|---|
| gpt-oss-120b | 147/160 | 91.9% [87%–95%] | $0.32 | $0.34 | 930 / 294 | measured |
| Gemini 3.1 Flash-Lite | 144/160 | 90.0% [84%–94%] | $0.40 | $0.45 | 949 / 112 | measured |
| Claude Haiku 5.5 | 148/160 | 92.5% [87%–96%] | $0.48 | $0.52 | 1,403 / 688 | measured |
| Gemini 3.8 Flash | 156/160 | 97.5% [94%–99%] | $3.62 | $3.72 | 949 / 777 | measured |
| Gemini 4 Argon | 154/160 | 96.2% [92%–98%] | $3.92 | $4.08 | 978 / 197 | measured |
| Claude Sonnet 5.5 | 156/160 | 97.5% [94%–99%] | $5.12 | $5.25 | 1,278 / 256 | measured |
| Claude Fable 5.2 | 156/160 | 97.5% [94%–99%] | $10.89 | $11.17 | 856 / 101 | estimated |
| Claude Opus 5.5 | 155/160 | 96.9% [93%–99%] | $11.59 | $11.96 | 1,278 / 324 | measured |
| Claude Fable 5.1 | 154/160 | 96.2% [92%–98%] | $25.22 | $26.20 | 1,403 / 224 | measured |
Table 1. Every model on the same 160 items (80 customer e-mail replies graded against a policy and the order records, 80 invoices into 11 fields). Brackets: 95% Wilson interval. “Tokens” says whether token counts came from the API’s usage field (measured) or were counted from the text (estimated).
| Model | Support | Tool calls | Extraction |
|---|---|---|---|
| gpt-oss-120b | 67/80 | 72/80 | 80/80 |
| Gemini 3.1 Flash-Lite | 64/80 | 77/80 | 80/80 |
| Claude Haiku 5.5 | 68/80 | 80/80 | 80/80 |
| Gemini 3.8 Flash | 76/80 | 80/80 | 80/80 |
| Gemini 4 Argon | 74/80 | 80/80 | 80/80 |
| Claude Sonnet 5.5 | 76/80 | 80/80 | 80/80 |
| Claude Fable 5.2 | 76/80 | not run | 80/80 |
| Claude Opus 5.5 | 75/80 | 80/80 | 80/80 |
| Claude Fable 5.1 | 74/80 | 79/80 | 80/80 |
Table 2. Correct answers per task, 80 items each. Tool calling (7 strict-schema tools) ran on the models served through the API only.
Routing
A router sends each request to a cheaper model when that model is as good as the best one on that kind of request. We simulated one on the 240 items of the 8 API models: split the items in half at random, pick per segment the cheapest model whose accuracy on the first half equals the best any model reaches there (otherwise the best overall model), then score both choices on the second half. Repeated 500 times.
| Router | Cost saved (mean) | 5th–95th pct | Accuracy change | 5th–95th pct |
|---|---|---|---|---|
| Per segment (support intent, tool kind, invoice layout) | 82.7% | 67%–94% | −1.4 pts | −4.2 to +0.8 |
| Per task (support, tools, extraction) | 51.2% | 40%–57% | −0.4 pts | −2.5 to +0.0 |
| Per item, with hindsight (cannot be built) | 89.8% | – | accuracy 99.6% | – |
Table 3. Cost saved and accuracy change against always using the best overall model, on held-out items. The per-segment router took the cost from $3.99 to $0.65 per 1,000 answers. Including the two models without tool calls on the 160 support and extraction items gives a 78.3% saving at −1.9 points.
Caching
We sent the same prompt prefix of about 6,700 tokens five more times to each model and read the cached-token count from the API’s usage field. Claude Sonnet 5.5 and Opus 5.5 reported a cache hit on every repeat: 93.1% lower input cost at list prices. The three Gemini models reported no cached tokens through our gateway, so for them a saving is not measured. gpt-oss-120b reported hits on 4 of 5 repeats (39% lower input cost). In the benchmark run itself, the cached tokens the API reported were worth:
| Model | Prompt tokens | Cached (reported) | Saving at list prices |
|---|---|---|---|
| Claude Sonnet 5.5 | 381,450 | 248,946 | 37% |
| Claude Opus 5.5 | 381,450 | 248,420 | 34% |
| Gemini 3.8 Flash | 261,310 | 0 | 0% |
| Gemini 3.1 Flash-Lite | 261,310 | 0 | 0% |
| Gemini 4 Argon | 270,738 | 0 | 0% |
| gpt-oss-120b | 226,526 | 141,376 | 16% |
| Claude Haiku 5.5 | 415,370 | 126,164 | 11% |
| Claude Fable 5.1 | 415,370 | 126,164 | 19% |
Table 4. Prompt tokens and the cached tokens reported in the benchmark run, and the saving at list prices (gross of any cache-write premium, which the gateway does not report). Claude Haiku 5.5 and Claude Fable 5.1 received the same prompts and reported the same cache hits, so their token counts match; the saving differs because it is a share of each model’s own list cost, and their list prices and output lengths differ.
How we measured
Items. The three main sets of MigrationBench, 80 items each, all fictional: customer e-mails to an outdoor store with its policy and order records, requests to a support agent with 7 strict-schema tools, and supplier invoices into 11 fields. Tools and extraction are scored by code; support replies by code checks plus an LLM judge.
Cost. The token counts of every response (from the API’s usage field, hidden reasoning tokens included) times the official list price read on 12 November 2026 from each provider’s pricing page (URL per model in summary.json). gpt-oss-120b is open-weight and sold by several hosts; we use Groq’s list price. Costs ignore caching; caching is measured separately above. Cost per correct answer = total cost ÷ correct answers.
Models. Claude Sonnet 5.5, Claude Opus 5.5, Gemini 3.8 Flash, Gemini 3.1 Flash-Lite, Gemini 4 Argon, gpt-oss-120b, Claude Haiku 5.5, Claude Fable 5.1, Claude Fable 5.2. API models were called through one OpenAI-compatible gateway at temperature 0 with a fixed seed. Claude Fable 5.2 ran through the vendor’s Claude Code CLI client, with no temperature or seed control and without the tool set; its tokens are counted from the text, so hidden reasoning is not counted. Not run: GPT-6.1 Sol, GPT-6.1 Terra, GPT-6 Luna, GPT-5.6 Sol (not available on the run date).
Judges. Support verdicts come from Gemini 4 Carbon. On the 480 replies that Claude Opus 5.5 also judged in MigrationBench, the two agreed on 456; on 240 re-run Claude replies, a second judge (Claude Opus 5.5) agreed with Gemini 4 Carbon on 231.
What the numbers cover. One run per item at list prices on one day. All models were called through one OpenAI-compatible gateway; provider-native APIs may report different token counts and latency. List prices change (Gemini 4 Argon’s doubles on 1 December 2026 and Gemini 3.8 Flash’s on 1 January 2027). The items are short and the accuracy differences between the top models are within the intervals in Table 1; the cost differences are not.
Data
- summary.json (48 KB): every number on this page
- items.csv (315 KB): one row per answer: model, task, correct, tokens, cost
- per_task.csv (2 KB): accuracy and cost per model and task
- table_all_tasks_proxy.csv (1 KB): all three tasks, API models
- table_paired_subset.csv (1 KB): Table 1